For students and new grads applying to internships

Land your first role
with ARTie

Your own coding agent tailors your resume to each posting, using only what you've actually done. It runs on your computer, and there's no account to create.

Free to use · Works with Claude Code and Codex · Install steps

Writing your first real resume is hard

Not because you haven't done anything. Turning what you've done into what a recruiter scans for is a separate skill.

  • You've never written a real resume

    Coursework, a hackathon, a part-time job. It all counts, but nobody shows you what belongs on the page or how to word it.

  • You don't know what recruiters want

    Ten templates, ten opinions. The posting says what the team needs, but turning that into your resume is its own skill.

  • One resume, fifty postings

    Tailoring each application by hand is the advice everyone gives and few people follow. It takes a lot of time per job.

The method

How ARTie tailors a resume

Your coding agent does the reading and writing. ARTie keeps your facts and your preferences, and checks every change.

  1. Step 1
    Read you

    Your agent reads what you've done

    Claude Code or Codex reads your resume, your LinkedIn export and your project folders, and saves what you've done to a knowledge graph on your computer. Tell it to fix anything it got wrong.

    • Built once with /art:setup
    • Stays on your machine
  2. Step 2
    Read the job

    Then it reads the posting

    Give /art:tailor a job posting or a link. Your agent pulls out what the role requires, and ART saves the job so you can come back to it.

    • Paste text or a URL
    • One saved job per application
  3. Step 3
    Tailor

    It tailors from what you've approved

    Your agent starts from your approved bullets and your saved preferences, like "lead with Python" or "never mention Kafka". It shows you the plan and waits for your OK before anything changes.

    • Rewords and reorders, not a blank-page rewrite
    • You approve the plan first
  4. Step 4
    Check

    ART's gates check the result

    Each rewritten bullet has to cite something in your graph, and its numbers and names have to match that evidence. Your pins and bans are enforced. The result has to fit on one page, at two lines per bullet or fewer. A change that fails is reverted, and your agent is told why.

    • No fabrication
    • Your pins and bans
    • One page
  5. Step 5
    Render

    It renders a LaTeX PDF

    ART writes the .tex and the PDF to a folder on your computer. Every version is kept: /art:history lists them and /art:revert brings an old one back.

    • PDF needs tectonic or pdflatex
    • Otherwise you get the .tex file

See it run

One tailoring run, start to finish

This is a replay of a real ARTie run on a sample student profile and a sample internship posting. Neither is a real person or a real company.

/art:setup resume.md, plus the READMEs of three repos that aren't on my resume

I'll read resume.md and the three READMEs and store what they say: your degree, roles, projects and skills, with the bullets exactly as written. I won't add anything the files don't state.

upsert_itemsfrom ART

arguments
{  "records": [    {      "kind": "education",      "data": {        "institution": "Alder Valley State University",        "degree": "B.S. Computer Science, Data Science minor",        "end_date": "Expected June 2027",        "gpa": "3.7"      }    },    {      "kind": "experience",      "data": {        "company": "Kestrel Print & Sign",        "title": "Web Developer Intern",        "start_date": "2026-06",        "end_date": "2026-08",        "bullets": [          "Built a React storefront for custom print orders that replaced the shop's phone-and-email process.",          "Added a Node and PostgreSQL order API with 12 endpoints and a staging environment.",          "… 3 more"        ]      }    },    "… 24 more"  ],  "source": "resume.md"}
{  "counts": {    "created": 26  },  "results": [    {      "index": 0,      "key": "edu:alder valley state university|b.s. computer science, data science minor",      "kind": "education",      "message": null,      "status": "created"    },    {      "index": 1,      "key": "exp:web developer intern|kestrel print & sign",      "kind": "experience",      "message": null,      "status": "created"    },    "… 24 more"  ],  "…": "1 more fields"}

Stored 26 records from resume.md. Now the three repos.

upsert_itemsfrom ART

arguments
{  "records": [    {      "kind": "project",      "data": {        "name": "Checkout A/B Test",        "repo_url": "https://github.com/riley-park-demo/checkout-ab-test",        "description": "A class project that compares two checkout flows on a mock store.",        "blurbs": [          "Designed an A/B test of two checkout flows on a mock store, choosing the sample size of 8,000 sessi…",          "Analyzed the results with a two-proportion z-test in Python (statsmodels); the one-page flow raised…",          "… 2 more"        ]      }    },    {      "kind": "project",      "data": {        "name": "Subscription Churn Model",        "repo_url": "https://github.com/riley-park-demo/subscription-churn",        "description": "Predicts which subscribers cancel, from a public customer dataset.",        "blurbs": [          "Engineered 12 features from the customer table in SQL, such as tenure and support-call counts.",          "Trained logistic regression and gradient-boosted models in scikit-learn, reaching 0.84 AUC on a hel…",          "… 2 more"        ]      }    },    "… 5 more"  ],  "source": "github READMEs"}
{  "counts": {    "created": 7  },  "results": [    {      "index": 0,      "key": "proj:checkout a/b test",      "kind": "project",      "message": null,      "status": "created"    },    {      "index": 1,      "key": "proj:subscription churn model",      "kind": "project",      "message": null,      "status": "created"    },    "… 5 more"  ],  "…": "1 more fields"}

Stored 7 more: the A/B test, churn and retail projects, and the skills they name. Now your header.

update_profilefrom ART

arguments
{  "fields": {    "name": "Riley Park",    "email": "riley.park@example.com",    "phone": "(555) 010-0142",    "linkedin_url": "https://linkedin.com/in/riley-park-demo",    "github_username": "riley-park-demo"  }}
{  "email": "riley.park@example.com",  "error": null,  "github_username": "riley-park-demo",  "linkedin_url": "https://linkedin.com/in/riley-park-demo",  "location": null,  "name": "Riley Park",  "phone": "(555) 010-0142",  "portfolio_url": null}

list_itemsfrom ART

arguments
{}
{  "error": null,  "items": [    {      "key": "edu:alder valley state university|b.s. computer science, data science minor",      "kind": "education",      "title": "Alder Valley State University — B.S. Computer Science, Data Science minor"    },    {      "key": "exp:shift lead|fernhollow coffee",      "kind": "experience",      "title": "Shift Lead @ Fernhollow Coffee"    },    {      "key": "exp:teaching assistant|alder valley state university, department of computer science",      "kind": "experience",      "title": "Teaching Assistant @ Alder Valley State University, Department of Computer Science"    },    "… 30 more"  ]}

Your graph holds 3 roles, 7 projects, 22 skills and your degree: more than fits on one page. Paste a posting whenever you're ready.

/art:tailor Brightwell Market, Data Science Intern, Growth Analytics, Summer 2027 (sample posting, 22 lines pasted). Compare it with my usual resume: resume.md alone.

Reading the posting, then checking whether you've saved any preferences.

art_briefingfrom ART

arguments
{  "role_family": "data_science"}
{  "pins": [],  "preferences": [],  "counts": {    "job_cards": 0,    "job_rules": 0,    "pins": 0,    "preferences": 0  },  "role_family": "data_science",  "…": "5 more fields"}

No saved preferences yet. Opening the job with the 6 requirements I pulled out of the posting.

open_jobfrom ART

arguments
{  "jd_text": "Data Science Intern, Growth Analytics, Summer 2027\nBrightwell Market (sample posting written for this demo)\nH…",  "requirements": [    {      "text": "The candidate is pursuing a B.S. or M.S. in computer science, statistics, data science or a related field.",      "type": "required",      "criticality": 2,      "terms": [        "computer science",        "data science"      ],      "source_section": "Required qualifications"    },    {      "text": "The candidate has experience with SQL and Python, including pandas.",      "type": "required",      "criticality": 5,      "terms": [        "SQL",        "Python",        "pandas"      ],      "source_section": "Required qualifications"    },    {      "text": "The candidate has designed or analyzed experiments, for example A/B tests and significance testing.",      "type": "required",      "criticality": 5,      "terms": [        "A/B test",        "experiments",        "significance",        "… 1 more"      ],      "source_section": "Required qualifications"    },    "… 3 more"  ],  "metadata": {    "title": "Data Science Intern, Growth Analytics, Summer 2027",    "company": "Brightwell Market",    "role_family": "data_science"  }}
{  "job_id": "eee6d702-4161-49f9-b50a-9706daf02877",  "title": "Data Science Intern, Growth Analytics, Summer 2027",  "company": "Brightwell Market",  "requirements": 6,  "role_family": "data_science",  "skill_matches": [    {      "requirement": 1,      "skill": "SQL",      "term": "sql",      "type": "required"    },    {      "requirement": 1,      "skill": "Python",      "term": "python",      "type": "required"    },    {      "requirement": 1,      "skill": "pandas",      "term": "pandas",      "type": "required"    },    "… 4 more"  ],  "unmatched_terms": [    {      "requirement": 2,      "term": "a/b test",      "type": "required"    },    {      "requirement": 2,      "term": "experiments",      "type": "required"    },    {      "requirement": 2,      "term": "significance",      "type": "required"    },    "… 9 more"  ],  "…": "8 more fields"}

ART matched 7 of the posting's terms to skills you already have. It doesn't guess at the ones it couldn't match, so I'll only use those words where your own bullets support them.

First, your usual resume as version 1, so there's something to compare against: what resume.md says, with the three repo projects left off. Nothing reworded.

execute_planfrom ART

arguments
{  "program": {    "job_id": "eee6d702-4161-49f9-b50a-9706daf02877",    "parent": null,    "nodes": [      {        "id": "d1",        "op": "delete",        "item_key": "proj:checkout a/b test",        "because": "user:my usual resume is resume.md, so leave the three repo projects off"      },      {        "id": "d2",        "op": "delete",        "item_key": "proj:subscription churn model",        "because": "user:my usual resume is resume.md, so leave the three repo projects off"      },      {        "id": "d3",        "op": "delete",        "item_key": "proj:retail sales dashboard",        "because": "user:my usual resume is resume.md, so leave the three repo projects off"      }    ],    "skills": [      "Python",      "Java",      "JavaScript",      "TypeScript",      "… 14 more"    ]  }}
{  "committed": true,  "node_id": "d671ec49-b05c-4154-820b-fa1548214c7c",  "line_budget": {    "budget": 60,    "cut_hints": [],    "lines_used": 52.94,    "over_by": -7.06  },  "violations": [],  "metrics": {    "final": {      "gates": {        "bullet_lines": [],        "citations": [],        "consistency": [],        "faithfulness": [],        "preferences": []      }    },    "…": "guards, targets and the ATS-style report left out"  }}

Reading your internship in full, so I cite its bullets by id.

get_itemfrom ART

arguments
{  "key": "exp:web developer intern|kestrel print & sign"}
{  "error": null,  "key": "exp:web developer intern|kestrel print & sign",  "kind": "experience",  "record": {    "bullets": [      "Built a React storefront for custom print orders that replaced the shop's phone-and-email process.",      "Added a Node and PostgreSQL order API with 12 endpoints and a staging environment.",      "Fixed 30 accessibility issues from an audit, raising the Lighthouse accessibility score from 71 to 96.",      "Set up GitHub Actions to run the test suite on every pull request.",      "… 1 more"    ],    "company": "Kestrel Print & Sign",    "description": "",    "end": "2026-08",    "id": "1e0608e1-0403-45a3-a3f1-40ee347be0d5",    "incomplete": false,    "missing": [],    "projects": [],    "start": "2026-06",    "title": "Web Developer Intern"  },  "variants": []}

suggest_actionsfrom ART

arguments
{  "job_id": "eee6d702-4161-49f9-b50a-9706daf02877"}
{  "error": null,  "floor": 0.1,  "items": [    {      "actions": [        {          "op": "keep",          "propensity": 0.3333333333333333        },        {          "op": "revise",          "propensity": 0.3333333333333333        },        "… 1 more"      ],      "approved_variants": 0,      "best_score": 0,      "item_key": "exp:web developer intern|kestrel print & sign",      "match": "no_match",      "propensity": null,      "source": "fallback",      "title": "Web Developer Intern @ Kestrel Print & Sign",      "variant": null    },    {      "actions": [        {          "op": "keep",          "propensity": 0.3333333333333333        },        {          "op": "revise",          "propensity": 0.3333333333333333        },        "… 1 more"      ],      "approved_variants": 0,      "best_score": 0,      "item_key": "exp:teaching assistant|alder valley state university, department of computer science",      "match": "no_match",      "propensity": null,      "source": "fallback",      "title": "Teaching Assistant @ Alder Valley State University, Department of Computer Science",      "variant": null    },    "… 5 more"  ],  "job_id": "eee6d702-4161-49f9-b50a-9706daf02877",  "node_id": "d671ec49-b05c-4154-820b-fa1548214c7c"}

No approved bullet variants yet, so I'll write from your source bullets. Here's the plan. Nothing changes until you say so.

  1. Projects first, above Experience: your best matches for this posting are projects.
  2. Projects: swap Checkout A/B Test, Subscription Churn Model and Retail Sales Dashboard in for Recycling Sorter, Budget Tracker and Portfolio Site. For the A/B result I'll add the 19% relative lift I worked out from your 3.1% and 3.7%.
  3. Web Developer Intern: lead with the SQL bullet, which the posting asks for, and cut the Node API and GitHub Actions bullets.
  4. Teaching Assistant: lead with the plain-language bullet and call it a "non-technical audience", the posting's words.
  5. Drop the Fernhollow Coffee job; the posting doesn't ask for it.
  6. Skills: Python, SQL, pandas, statsmodels and scikit-learn first; the web skills come off.

Campus Dining Recommender and everything else stays as you wrote it. Go ahead?

Written for this demo: the second item adds a figure that no source states, so the replay can show the check that catches it.

Looks good. Go ahead, and yes, drop the coffee shop job.

Running the plan through ART's checks.

execute_planfrom ART

arguments
{  "program": {    "job_id": "eee6d702-4161-49f9-b50a-9706daf02877",    "parent": "d671ec49-b05c-4154-820b-fa1548214c7c",    "nodes": [      {        "id": "n1",        "op": "revise",        "item_key": "exp:web developer intern|kestrel print & sign",        "bullets": "… 3 bullets, each citing its source",        "…": "2 more fields"      },      {        "id": "n2",        "op": "revise",        "item_key": "exp:teaching assistant|alder valley state university, department of computer science",        "bullets": "… 4 bullets, each citing its source",        "…": "2 more fields"      },      {        "id": "n3",        "op": "replace",        "item_key": "proj:recycling sorter",        "replacement_key": "proj:checkout a/b test",        "bullets": [          {            "text": "Analyzed the A/B test in Python with a two-proportion z-test (statsmodels) to check significance; the one-page flow raised conversion from 3.1% to 3.7%, a 19% relative lift (p = 0.03).",            "cites": [              "proj:checkout a/b test#b1"            ]          },          "… 3 more bullets"        ],        "…": "1 more fields"      },      {        "id": "n4",        "op": "replace",        "item_key": "proj:budget tracker",        "replacement_key": "proj:subscription churn model",        "bullets": "… 4 bullets, each citing its source",        "…": "1 more fields"      },      {        "id": "n5",        "op": "keep",        "item_key": "proj:campus dining recommender"      },      {        "id": "n6",        "op": "replace",        "item_key": "proj:portfolio site",        "replacement_key": "proj:retail sales dashboard",        "bullets": "… 3 bullets, each citing its source",        "…": "1 more fields"      },      {        "id": "n7",        "op": "delete",        "item_key": "exp:shift lead|fernhollow coffee",        "because": "user:approved dropping the Fernhollow Coffee job, which the posting does not ask for"      }    ],    "skills": [      "Python",      "SQL",      "pandas",      "… 7 more"    ],    "section_order": [      "education",      "projects",      "experience",      "skills"    ],    "host": {      "name": "claude-code"    }  }}
{  "committed": true,  "node_id": "722a41b7-b628-4248-8870-3d00ba148b48",  "nodes": [    {      "id": "n1",      "op": "revise",      "item_key": "exp:web developer intern|kestrel print & sign",      "status": "accepted",      "reason": null,      "…": "6 more fields"    },    {      "id": "n2",      "op": "revise",      "item_key": "exp:teaching assistant|alder valley state university, department of computer science",      "status": "accepted",      "reason": null,      "…": "6 more fields"    },    {      "id": "n7",      "op": "delete",      "item_key": "exp:shift lead|fernhollow coffee",      "status": "accepted",      "reason": "guard_waived: requested delete; mtld regressed 0.1352",      "…": "6 more fields"    },    {      "id": "n3",      "op": "replace",      "item_key": "proj:recycling sorter",      "status": "reverted",      "reason": "hard_gate: consistency ['consistency:Analyzed the A/B test in Python with a …:19%']",      "…": "6 more fields"    },    {      "id": "n4",      "op": "replace",      "item_key": "proj:budget tracker",      "status": "accepted",      "reason": null,      "…": "6 more fields"    },    {      "id": "n6",      "op": "replace",      "item_key": "proj:portfolio site",      "status": "accepted",      "reason": null,      "…": "6 more fields"    },    {      "id": "n5",      "op": "keep",      "item_key": "proj:campus dining recommender",      "status": "kept",      "reason": null,      "…": "6 more fields"    }  ],  "violations": [],  "…": "15 more fields"}

ART reverted one of my changes: the Checkout A/B Test swap. "19%" isn't in the bullet it cites. I worked that figure out myself, and ART only accepts numbers your own bullet states. Everything else went in as version 2. I'll resubmit the swap with your original 3.1% and 3.7%.

execute_planfrom ART

arguments
{  "program": {    "job_id": "eee6d702-4161-49f9-b50a-9706daf02877",    "parent": "722a41b7-b628-4248-8870-3d00ba148b48",    "nodes": [      {        "id": "n3",        "op": "replace",        "item_key": "proj:recycling sorter",        "replacement_key": "proj:checkout a/b test",        "bullets": [          {            "text": "Designed an A/B test of two checkout flows on a mock store, choosing the sample size of 8,000 sessions per variant with a power calculation before running it.",            "cites": [              "proj:checkout a/b test#b0"            ]          },          {            "text": "Analyzed the A/B test in Python with a two-proportion z-test (statsmodels) to check significance; the one-page flow raised conversion from 3.1% to 3.7% (p = 0.03).",            "cites": [              "proj:checkout a/b test#b1"            ]          },          {            "text": "Built a Streamlit dashboard that shows daily conversion and a 95% confidence interval for each variant.",            "cites": [              "proj:checkout a/b test#b2"            ]          },          {            "text": "Wrote a one-page memo with a recommendation for a non-technical audience of classmates who had not taken the course.",            "cites": [              "proj:checkout a/b test#b3"            ]          }        ],        "keywords": [          "A/B test",          "experiments",          "significance",          "dashboards",          "Streamlit",          "non-technical"        ]      }    ]  }}
{  "committed": true,  "node_id": "762b43ae-d229-4f78-9012-d528772a7552",  "parent": "722a41b7-b628-4248-8870-3d00ba148b48",  "nodes": [    {      "id": "n3",      "op": "replace",      "item_key": "proj:recycling sorter",      "status": "accepted",      "reason": null,      "improved": [        "coverage",        "relevance_density"      ],      "…": "5 more fields"    }  ],  "violations": [],  "…": "14 more fields"}

Committed as version 3. Here is what changed from version 1.

diff_nodesfrom ART

arguments
{  "from_node": "d671ec49-b05c-4154-820b-fa1548214c7c",  "to_node": "762b43ae-d229-4f78-9012-d528772a7552"}
{  "items": [    {      "bullets_added": [],      "bullets_removed": [        "Trained 6 new baristas on the register, the opening checklist and the espresso machine.",        "Reconciled the till against the day's sales report at the end of every shift.",        "Scheduled a team of 9 around class timetables using a shared spreadsheet.",        "… 1 more"      ],      "change": "removed",      "key": "exp:shift lead|fernhollow coffee",      "reordered": false,      "title": "Shift Lead @ Fernhollow Coffee"    },    {      "bullets_added": [        "Explained recursion and hash tables in plain language to a non-technical audience of students w…"      ],      "bullets_removed": [        "Explained recursion and hash tables in plain language to students with no programming backgroun…"      ],      "change": "revised",      "key": "exp:teaching assistant|alder valley state university, department of computer science",      "reordered": false,      "title": "Teaching Assistant @ Alder Valley State University, Department of Computer Science"    },    {      "bullets_added": [        "Wrote SQL queries that turn order data into a weekly sales report by product, which the owner u…"      ],      "bullets_removed": [        "Added a Node and PostgreSQL order API with 12 endpoints and a staging environment.",        "Set up GitHub Actions to run the test suite on every pull request.",        "Wrote SQL queries that report weekly sales by product, which the owner used to decide what to s…"      ],      "change": "revised",      "key": "exp:web developer intern|kestrel print & sign",      "reordered": false,      "title": "Web Developer Intern @ Kestrel Print & Sign"    },    "… 6 more"  ],  "skills_added": [    "statsmodels",    "scikit-learn",    "Streamlit",    "… 1 more"  ],  "skills_removed": [    "Java",    "JavaScript",    "TypeScript",    "… 9 more"  ],  "…": "6 more fields"}

Now I'll render version 1, then version 3, as PDFs.

renderfrom ART

arguments
{  "job_id": "eee6d702-4161-49f9-b50a-9706daf02877",  "node_id": "d671ec49-b05c-4154-820b-fa1548214c7c"}
{  "node_id": "d671ec49-b05c-4154-820b-fa1548214c7c",  "pdf_path": "~/.art/applications/Brightwell_Market_Data_Science_Intern_Growth_Analytics_Summer_2027/res…",  "pages": 1,  "source": "generated",  "…": "5 more fields"}

renderfrom ART

arguments
{  "job_id": "eee6d702-4161-49f9-b50a-9706daf02877",  "node_id": "762b43ae-d229-4f78-9012-d528772a7552"}
{  "node_id": "762b43ae-d229-4f78-9012-d528772a7552",  "pdf_path": "~/.art/applications/Brightwell_Market_Data_Science_Intern_Growth_Analytics_Summer_2027/res…",  "pages": 1,  "source": "generated",  "…": "5 more fields"}

Done. The tailored resume fits on one page and is at ~/.art/applications/Brightwell_Market_Data_Science_Intern_Growth_Analytics_Summer_2027/resume.pdf. I rendered version 1 first for the comparison, so that file now holds the tailored one. Read it through before you send it.

Blocks with a green edge are what ART returned, captured from the run. The other lines, from the user and the agent, were written for this demo. Long answers are shortened where you see an ellipsis. Playback speed is fixed (about 88 seconds in all); it doesn't show how long ART took.

The same student, before and after

The student's knowledge graph holds more than fits on one page. Their usual page leads with web work. Tailored to a data science internship, the page leads with the projects the posting asks for. Both PDFs come from that same run, as whole pages, and the highlighted lines are the bullets that differ, found by comparing the PDFs' text.

Sample posting, written for this demo

Data Science Intern, Growth Analytics, Summer 2027

Brightwell Market Hybrid, 12 weeks

Neither the company nor the role is real. The list is what the agent read out of the posting's text.

What the posting asks for

  • Pursuing a B.S. or M.S. in a quantitative fieldrequired
  • SQL and Python, including pandasrequired
  • Design and analyze A/B testsrequired
  • Machine learning with scikit-learnrequired
  • Explain results to a non-technical audiencerequired
  • Dashboards, for example in Streamlit or Tableaupreferred
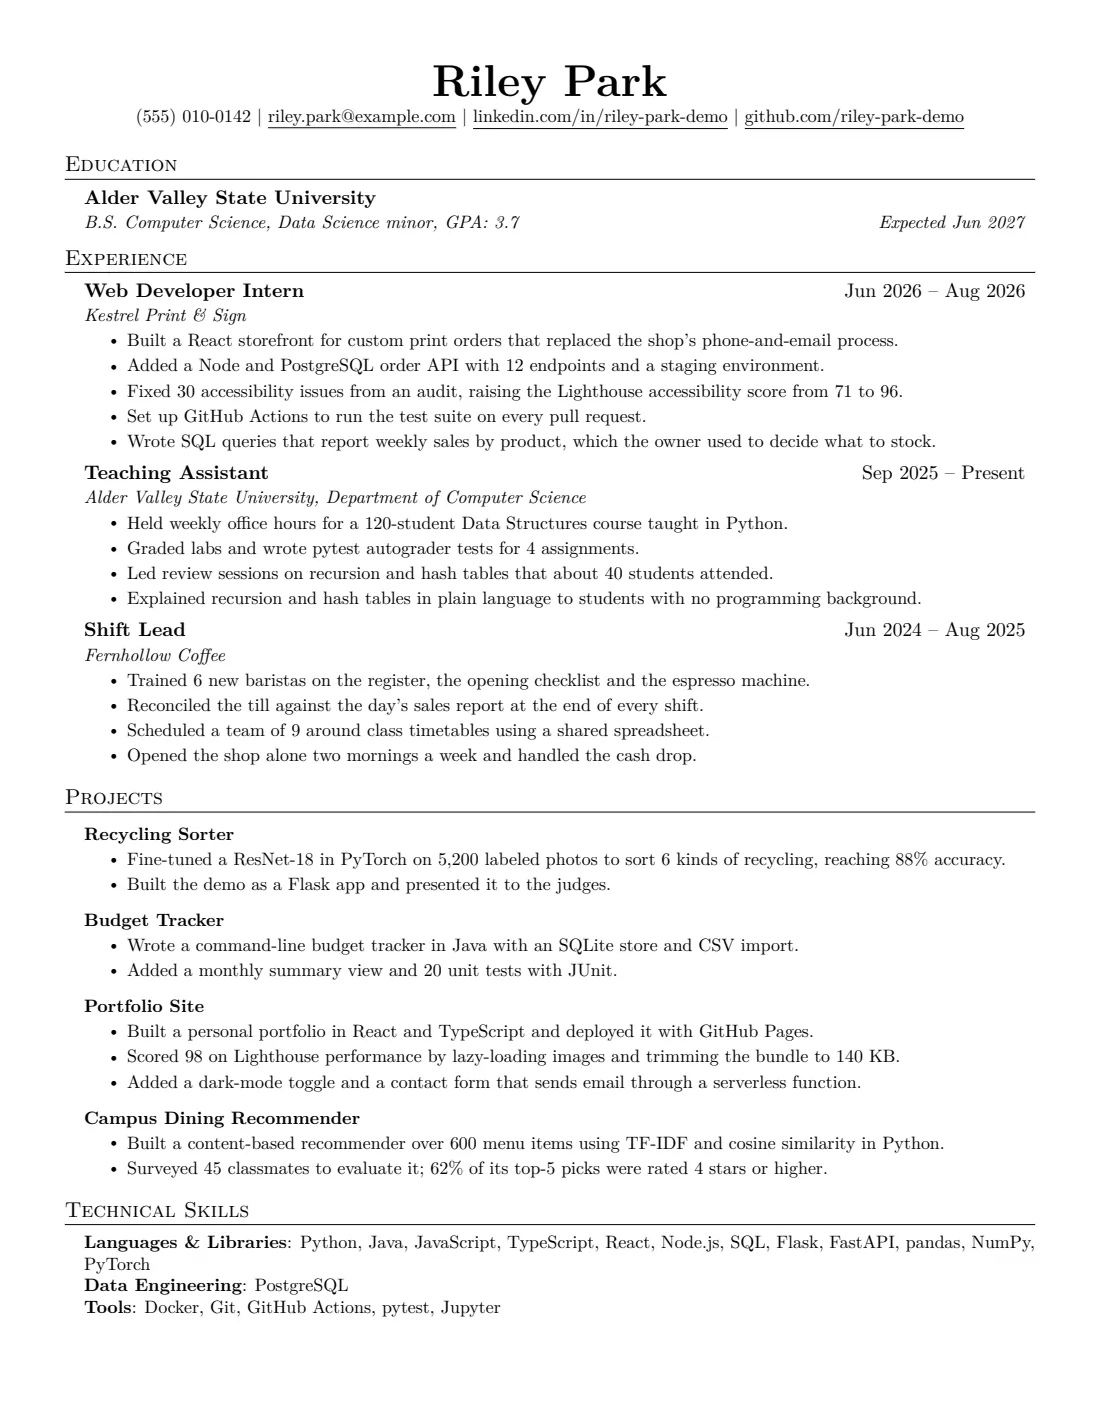
BeforeRiley's usual one-page resumeThe content of resume.md, laid out by ARTie from the knowledge graph. The three repo projects are left off and nothing is reworded. This is what Riley would send to every posting.
The student's usual one-page resume, laid out by ARTie from the sample knowledge graph. It leads with web development work. Lines that tailoring changes are highlighted in red. The changes are also listed as text below.

Open the before page full size

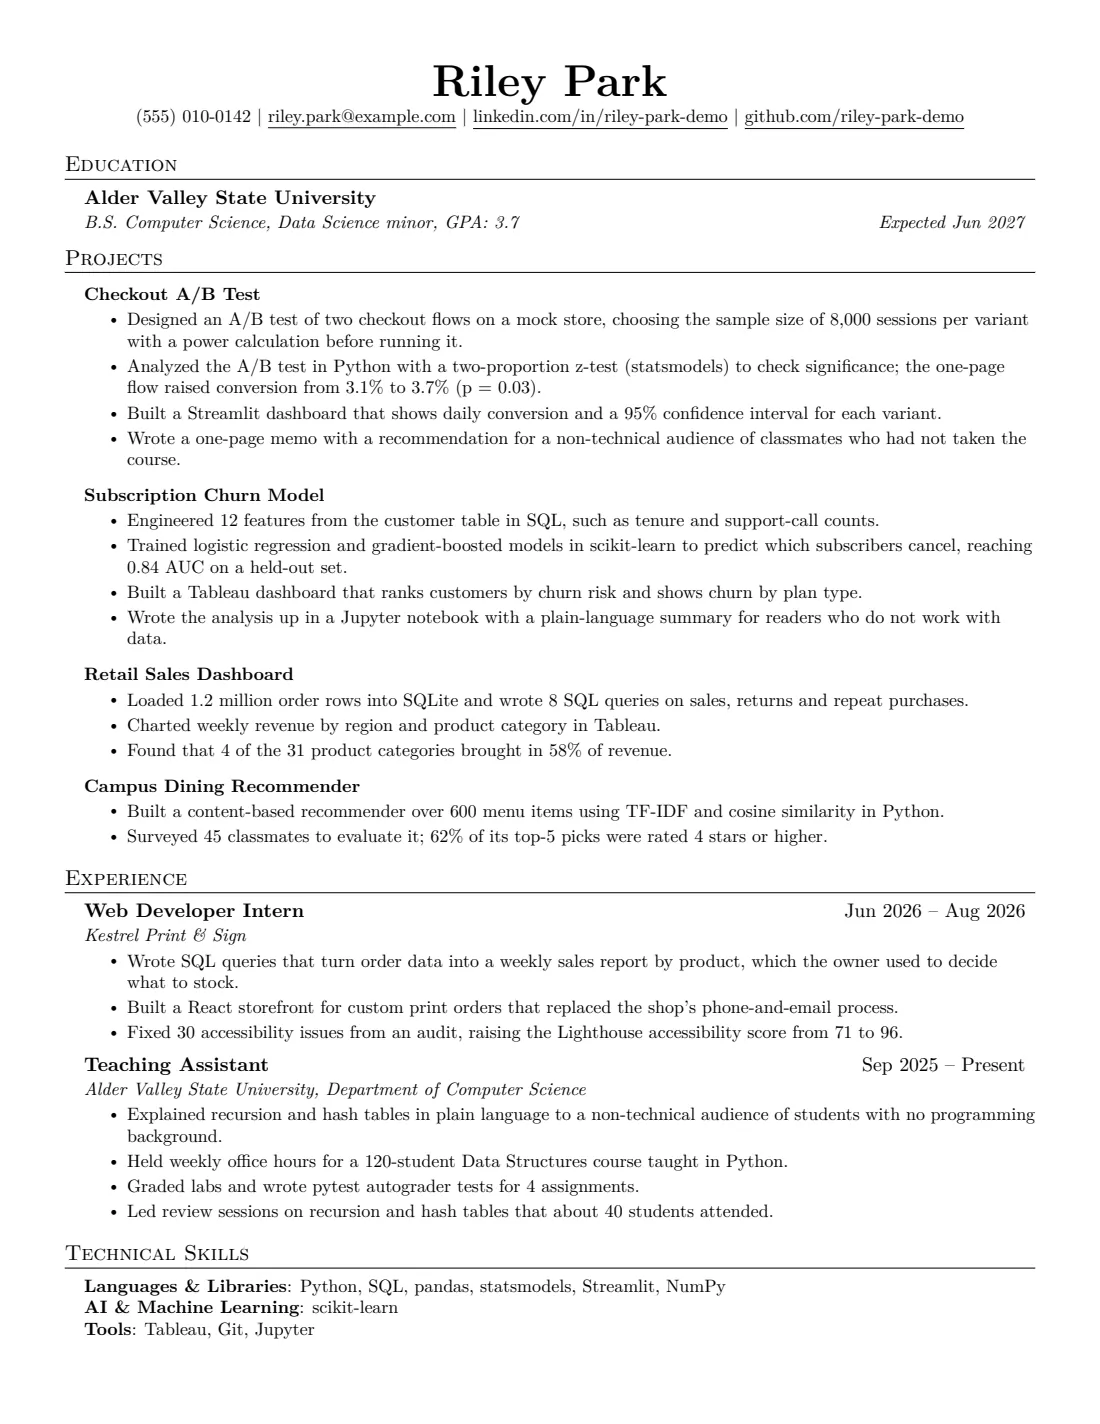
AfterTailored to Brightwell MarketVersion 3 from the same run, after ARTie's checks: still one page, and built only from bullets in the graph.
The same student's resume after tailoring to the sample data science internship. Projects now come first, led by the A/B test project, and the page is still one page. Lines that tailoring changed or added are highlighted in green. The changes are also listed as text below.

Open the after page full size

What changed, and which requirement it serves

Added from your graph
  • Checkout A/B Test is now the first project of 4, in place of Recycling Sorter. It was not on the usual page; it comes from a repo README in the graph.

    Serves Design and analyze A/B tests; Explain results to a non-technical audience

  • Subscription Churn Model is now the second project of 4, in place of Budget Tracker. It was not on the usual page; it comes from a repo README in the graph.

    Serves Machine learning with scikit-learn; Explain results to a non-technical audience

  • Retail Sales Dashboard is now the third project of 4, in place of Portfolio Site. It was not on the usual page; it comes from a repo README in the graph.

    Serves SQL and Python, including pandas; Dashboards, for example in Streamlit or Tableau

Moved up
  • Projects now sits above Experience.

    Serves SQL and Python, including pandas; Design and analyze A/B tests

  • Under Web Developer Intern, bullet 5 moves to bullet 1: Wrote SQL queries that turn order data into a weekly sales report by product, which the owner used to decide what to stock.

    Serves SQL and Python, including pandas

  • Under Teaching Assistant, bullet 4 moves to bullet 1: Explained recursion and hash tables in plain language to a non-technical audience of students with no programming background.

    Serves Explain results to a non-technical audience

Reworded
  • Your wording Wrote SQL queries that report weekly sales by product, which the owner used to decide what to stock.

    Now Wrote SQL queries that turn order data into a weekly sales report by product, which the owner used to decide what to stock.

    Serves SQL and Python, including pandas

  • Your wording Explained recursion and hash tables in plain language to students with no programming background.

    Now Explained recursion and hash tables in plain language to a non-technical audience of students with no programming background.

    Serves Explain results to a non-technical audience

  • Your wording Analyzed the results with a two-proportion z-test in Python (statsmodels); the one-page flow raised conversion from 3.1% to 3.7% (p = 0.03).

    Now Analyzed the A/B test in Python with a two-proportion z-test (statsmodels) to check significance; the one-page flow raised conversion from 3.1% to 3.7% (p = 0.03).

    Serves Design and analyze A/B tests

  • Your wording Wrote a one-page memo with a recommendation for classmates who had not taken the course.

    Now Wrote a one-page memo with a recommendation for a non-technical audience of classmates who had not taken the course.

    Serves Explain results to a non-technical audience

  • Your wording Trained logistic regression and gradient-boosted models in scikit-learn, reaching 0.84 AUC on a held-out set.

    Now Trained logistic regression and gradient-boosted models in scikit-learn to predict which subscribers cancel, reaching 0.84 AUC on a held-out set.

    Serves Machine learning with scikit-learn

Cut
  • Under Web Developer Intern, Added a Node and PostgreSQL order API with 12 endpoints and a staging environment. comes off. The posting asks for data work, not web infrastructure.

  • Under Web Developer Intern, Set up GitHub Actions to run the test suite on every pull request. comes off. The posting asks for data work, not web infrastructure.

  • Shift Lead, Fernhollow Coffee comes off: the whole role, 4 bullets. The posting asks for data work, and the page is full without it.

  • Recycling Sorter is swapped for Checkout A/B Test.

  • Budget Tracker is swapped for Subscription Churn Model.

  • Portfolio Site is swapped for Retail Sales Dashboard.

Skills trimmed
  • 18 skills become 10. The page now leads with Python, SQL, pandas, statsmodels, scikit-learn.

    Added statsmodels, scikit-learn, Streamlit, Tableau

    Taken off Java, JavaScript, TypeScript, React, Node.js, PostgreSQL, Flask, FastAPI, PyTorch, Docker, GitHub Actions, pytest

    ServesDesign and analyze A/B tests; Machine learning with scikit-learn; Dashboards, for example in Streamlit or Tableau; SQL and Python, including pandas

The changes themselves are ARTie's own comparison of the two versions. Each requirement is matched to a change from the posting terms the plan named for that item. The reasons given for cuts were written for this demo.

Read every changed line as text
  • After Projects

    After Checkout A/B Test

    After Designed an A/B test of two checkout flows on a mock store, choosing the sample size of 8,000 sessions per variant with a power calculation before running it.

    After Analyzed the A/B test in Python with a two-proportion z-test (statsmodels) to check significance; the one-page flow raised conversion from 3.1% to 3.7% (p = 0.03).

    After Built a Streamlit dashboard that shows daily conversion and a 95% confidence interval for each variant.

    After Wrote a one-page memo with a recommendation for a non-technical audience of classmates who had not taken the

    After course.

    After Subscription Churn Model

    After Engineered 12 features from the customer table in SQL, such as tenure and support-call counts.

    After Trained logistic regression and gradient-boosted models in scikit-learn to predict which subscribers cancel, reaching 0.84 AUC on a held-out set.

    After Built a Tableau dashboard that ranks customers by churn risk and shows churn by plan type.

    After Wrote the analysis up in a Jupyter notebook with a plain-language summary for readers who do not work with data.

    After Retail Sales Dashboard

    After Loaded 1.2 million order rows into SQLite and wrote 8 SQL queries on sales, returns and repeat purchases.

    After Charted weekly revenue by region and product category in Tableau.

    After Found that 4 of the 31 product categories brought in 58% of revenue.

    After Campus Dining Recommender

    After Built a content-based recommender over 600 menu items using TF-IDF and cosine similarity in Python.

    After Surveyed 45 classmates to evaluate it; 62% of its top-5 picks were rated 4 stars or higher.

  • After Wrote SQL queries that turn order data into a weekly sales report by product, which the owner used to decide what to stock.

  • Before Added a Node and PostgreSQL order API with 12 endpoints and a staging environment.

  • Before Set up GitHub Actions to run the test suite on every pull request.

    Before Wrote SQL queries that report weekly sales by product, which the owner used to decide what to stock.

  • After Explained recursion and hash tables in plain language to a non-technical audience of students with no programming background.

  • Before Explained recursion and hash tables in plain language to students with no programming background.

    Before Shift Lead Jun 2024 – Aug 2025

    Before Fernhollow Coffee

    Before Trained 6 new baristas on the register, the opening checklist and the espresso machine.

    Before Reconciled the till against the day’s sales report at the end of every shift.

    Before Scheduled a team of 9 around class timetables using a shared spreadsheet.

    Before Opened the shop alone two mornings a week and handled the cash drop.

    Before Projects

    Before Recycling Sorter

    Before Fine-tuned a ResNet-18 in PyTorch on 5,200 labeled photos to sort 6 kinds of recycling, reaching 88% accuracy.

    Before Built the demo as a Flask app and presented it to the judges.

    Before Budget Tracker

    Before Wrote a command-line budget tracker in Java with an SQLite store and CSV import.

    Before Added a monthly summary view and 20 unit tests with JUnit.

    Before Portfolio Site

    Before Built a personal portfolio in React and TypeScript and deployed it with GitHub Pages.

    Before Scored 98 on Lighthouse performance by lazy-loading images and trimming the bundle to 140 KB.

    Before Added a dark-mode toggle and a contact form that sends email through a serverless function.

    Before Campus Dining Recommender

    Before Built a content-based recommender over 600 menu items using TF-IDF and cosine similarity in Python.

    Before Surveyed 45 classmates to evaluate it; 62% of its top-5 picks were rated 4 stars or higher.

  • Before Languages & Libraries: Python, Java, JavaScript, TypeScript, React, Node.js, SQL, Flask, FastAPI, pandas, NumPy,

    Before PyTorch

    Before Data Engineering: PostgreSQL

    Before Tools: Docker, Git, GitHub Actions, pytest, Jupyter

    After Languages & Libraries: Python, SQL, pandas, statsmodels, Streamlit, NumPy

    After AI & Machine Learning: scikit-learn

    After Tools: Tableau, Git, Jupyter

These come from comparing the two PDFs' text bullet by bullet. A bullet moved to a new place shows once as removed and once as added.
Why you can trust it

It never invents experience you don't have

The quickest way to make a resume match a posting is to add things that aren't true. It's also the quickest way to fall apart in an interview, so ARTie is built to refuse it.

Every rewritten bullet has to cite something in your knowledge graph, and ARTie rejects a plan that names something your graph doesn't hold. Numbers and names are checked against the cited evidence, and anything you've banned stays off the page.

You approve the plan before it's applied, and you can edit any line yourself in the local editor (art ui). Read the PDF before you send it, as you would with any resume.

What tailoring changes

Wording
Your bullets, reworded from your approved versions
Emphasis
The most relevant projects and roles move up
Skills
Ranked and trimmed to what the posting asks for
Layout
Section order chosen for the role, on one page

What it never changes

The facts. What's in your knowledge graph, such as your employers, titles and what you built, stays as you recorded it, and tailoring can only cite it. The one thing that can vary by posting is a rule you answer yourself, like an expected graduation date.

Before you start

Who it's for and what you need

ARTie is for students and new grads applying to internships and entry-level roles, who are comfortable running Claude Code or Codex. It's a plugin for those tools, not a website. It's free to use, and the code is public on GitHub.

  • Claude Code or Codex

    Your own plan. Your agent's model does the reading and writing; ARTie never pays for or calls a text-writing model.

  • uv

    The Python tool runner that starts ARTie. On the first start, uv downloads ARTie, so you need a network connection once.

  • tectonic or pdflatex

    Only for PDFs. Without either you still get the .tex file.

See the install steps

Questions

Does it write my resume from scratch?

No. ARTie starts from what you've recorded: your resume, your LinkedIn export, your project folders, and the bullets you've approved. Your agent rewords those for each posting, cites where each bullet came from, and shows you the plan before applying it. If you don't have a resume yet, start with whatever you do have, like a rough draft or a project folder.

Do I need an API key?

No. ARTie makes no calls to a text-writing model, so there's nothing to pay for beyond your own Claude Code or Codex plan, and every check runs without a key.

Optional: strengthen the checks with Jev. If you have a TypeSafe API key, ARTie can use it to ask TypeSafe's Jev a few narrow questions that plain rules answer less well. It catches a reworded claim its cited source doesn't back, catches a banned topic mentioned in other words, and picks the best approved bullet for a job more often. The privacy note above says what those requests carry.

Where is my data stored?

On your computer. The knowledge graph, your preferences and every resume version are in ~/.art/art.db (or the folder in ART_DATA_DIR), and the rendered files go to ~/.art/applications/. What your own agent sends to its model provider is governed by that provider. If you turn on the optional Jev upgrade with a TypeSafe key, its checks send some text to TypeSafe too; the privacy note above says exactly what.

Will ARTie get me past applicant tracking systems (ATS)?

ARTie can't promise that, and it doesn't try to. It reports an ATS-style keyword score for each version, but it never optimizes for it and never promises one. That score only ever goes up as you add words, so chasing it rewards stuffing in keywords and penalizes cutting weak bullets. ARTie's checks look at different things: whether each bullet is supported by your history, whether you cover the posting's actual requirements, and whether it fits on one page.

Your experience is enough.
Let's write it down properly.

Start with whatever you have, even a rough draft and a project folder. Installing takes two commands in Claude Code.

Install in Claude Code
  • Resume
  • LinkedIn export
  • Project folders